
930 kr
Skickas inom 3-6 vardagar
930 kr
Skickas inom 3-6 vardagar
1 523 kr
Skickas inom 10-15 vardagar
1 523 kr
Skickas inom 10-15 vardagar
Taylor & Francis Ltd
3 000 kr
Skickas inom 10-15 vardagar
989 kr
Läs direkt efter köp
989 kr
Läs direkt efter köp
1 000 kr
Läs direkt efter köp
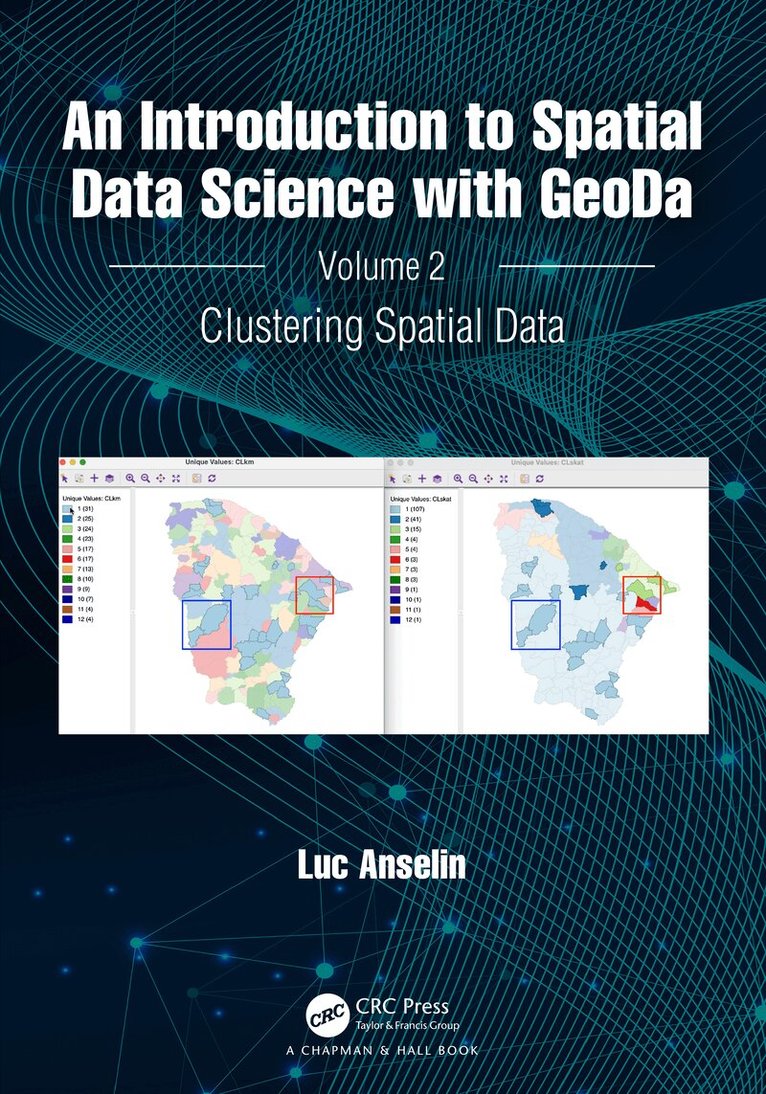
This book is the second in a two-volume series that introduces the field of spatial data science. It moves beyond pure data exploration to the organization of observations into meaningful groups, i.e., spatial clustering. This constitutes an important component of so-called unsupervised learning, a major aspect of modern machine learning.
The distinctive aspects of the book are both to explore ways to spatialize classic clustering methods through linked maps and graphs, as well as the explicit introduction of spatial contiguity constraints into clustering algorithms. Leveraging a large number of real-world empirical illustrations, readers will gain an understanding of the main concepts and techniques and their relative advantages and disadvantages. The book also constitutes the definitive user’s guide for these methods as implemented in the GeoDa open source software for spatial analysis.
It is organized into three major parts, dealing with dimension reduction (principal components, multidimensional scaling, stochastic network embedding), classic clustering methods (hierarchical clustering, k-means, k-medians, k-medoids and spectral clustering), and spatially constrained clustering methods (both hierarchical and partitioning). It closes with an assessment of spatial and non-spatial cluster properties.
The book is intended for readers interested in going beyond simple mapping of geographical data to gain insight into interesting patterns as expressed in spatial clusters of observations. Familiarity with the material in Volume 1 is assumed, especially the analysis of local spatial autocorrelation and the full range of visualization methods.
1 015 kr
Läs direkt efter köp
This book is the second in a two-volume series that introduces the field of spatial data science. It moves beyond pure data exploration to the organization of observations into meaningful groups, i.e., spatial clustering. This constitutes an important component of so-called unsupervised learning, a major aspect of modern machine learning.
The distinctive aspects of the book are both to explore ways to spatialize classic clustering methods through linked maps and graphs, as well as the explicit introduction of spatial contiguity constraints into clustering algorithms. Leveraging a large number of real-world empirical illustrations, readers will gain an understanding of the main concepts and techniques and their relative advantages and disadvantages. The book also constitutes the definitive user’s guide for these methods as implemented in the GeoDa open source software for spatial analysis.
It is organized into three major parts, dealing with dimension reduction (principal components, multidimensional scaling, stochastic network embedding), classic clustering methods (hierarchical clustering, k-means, k-medians, k-medoids and spectral clustering), and spatially constrained clustering methods (both hierarchical and partitioning). It closes with an assessment of spatial and non-spatial cluster properties.
The book is intended for readers interested in going beyond simple mapping of geographical data to gain insight into interesting patterns as expressed in spatial clusters of observations. Familiarity with the material in Volume 1 is assumed, especially the analysis of local spatial autocorrelation and the full range of visualization methods.
1 687 kr
Skickas inom 10-15 vardagar
1 957 kr
Skickas inom 10-15 vardagar
2 557 kr
Läs direkt efter köp
1 632 kr
Skickas inom 10-15 vardagar
1 957 kr
Skickas inom 10-15 vardagar
734 kr
Läs direkt efter köp
551 kr
Skickas inom 10-15 vardagar
2 174 kr
Läs direkt efter köp